ZutaCore, a developer of two-phase, direct-to-chip liquid cooling technology, has raised a $100 million Series C round to expand its cooling platform for AI data centers, according to a report published by Pulse 2.0 on June 6, 2026. The reported purpose of the raise is to scale the company’s platform as AI workloads push rack power densities beyond what air cooling can handle.
Executive Summary
The headline fact is simple: ZutaCore has secured $100 million in Series C funding to expand its AI data center cooling platform. At that size, the round places ZutaCore among the better-capitalized independent players in liquid cooling, a segment that has moved from niche engineering concern to strategic infrastructure category in roughly three years.
Why it matters: modern AI accelerators draw hundreds of watts per chip, and racks packed with them can reach power densities that air-based cooling physically cannot dissipate economically. That has turned the cooling layer — cold plates, coolant distribution units, dielectric fluids, and the engineering services around them — into one of the most actively funded niches in data center infrastructure. A $100 million commitment to a two-phase cooling specialist signals that investors believe the transition to liquid cooling is durable, and that there is room in the market beyond the largest incumbent thermal vendors.
Capital Keeps Flooding the Cooling Layer
Cooling used to be a line item buyers negotiated down. In the AI build-out it has become a gating constraint: if you cannot remove the heat, you cannot deploy the chips, no matter how much power or floor space you have. That inversion explains why investors have poured money into thermal specialists across every approach — single-phase cold plates, immersion tanks, rear-door heat exchangers, and two-phase systems like ZutaCore’s. A $100 million Series C for a company focused specifically on the AI cooling problem fits squarely into that pattern and suggests the funding window for the category remained open as of mid-2026.
The strategic logic for investors is that cooling vendors sit at a chokepoint. Every generation of AI accelerator raises thermal design power — the amount of heat a chip is engineered to shed — and each increase expands the addressable market for liquid cooling retrofits and new builds alike. The risk, equally, is that a crowded field of well-funded competitors compresses margins before any single vendor achieves scale.
What Two-Phase Cooling Actually Is — and Why It Is Contested Ground
Most liquid cooling deployed today is single-phase direct-to-chip: water or a water-glycol mix flows through a cold plate bolted to the processor, absorbs heat, and carries it away without changing state. Two-phase cooling instead uses an engineered dielectric fluid — a liquid that does not conduct electricity — that boils on contact with the hot chip. The phase change from liquid to vapor absorbs far more energy per unit of fluid than simple warming does, which is the core efficiency argument for the approach. ZutaCore has long positioned its platform around this waterless, two-phase principle, marketing it as eliminating the risk of water leaks onto expensive electronics.
The counterarguments are practical rather than theoretical. Two-phase systems are mechanically more complex, the specialty fluids cost more than water, and the fluorinated chemistries commonly used in the category face growing regulatory scrutiny in several jurisdictions. Meanwhile single-phase cold plates have become the default choice for the current generation of AI racks because hyperscalers understand water. ZutaCore’s raise is, implicitly, a bet that as chip power keeps climbing, the physics advantage of phase change wins share back from the simpler incumbent approach. The release, as reported, does not detail how the company plans to argue that case to buyers.
Winners, Losers, and the Consolidation Question
If the round accelerates ZutaCore’s manufacturing and deployment capacity, the immediate beneficiaries are data center operators seeking alternatives to water-based cooling — particularly in facilities where water usage or leak risk is a board-level concern. Chipmakers benefit from any credible expansion of thermal headroom, since cooling capability directly constrains how they can specify future products.
The open competitive question is whether independent cooling specialists remain independent. The thermal management sector has seen sustained acquisition interest from large industrial and infrastructure players, and a well-funded specialist with differentiated technology is a natural target. A Series C of this size can be read two ways: as fuel for a run at standalone scale, or as valuation-building ahead of eventual consolidation. The reporting available does not indicate which trajectory ZutaCore’s investors have in mind.
Background
ZutaCore is a specialist in waterless, two-phase, direct-to-chip liquid cooling, an approach it has promoted for years as a safer and denser alternative to water-based cold plates. The company sells the hardware and supporting infrastructure that let standard servers shed heat through a dielectric fluid that vaporizes on the processor, and it has positioned that platform squarely at the AI data center market as accelerator power consumption has climbed.
The broader context is a rapid industry transition: liquid cooling moved from a high-performance-computing niche to mainstream AI infrastructure in the mid-2020s, drawing venture capital, private equity, and acquisition interest across cold plate, immersion, and two-phase vendors alike. ZutaCore’s Series C lands in the middle of that capital wave.
Microsoft’s chief executive said the company’s newest AI data centers consume as little water annually as a typical restaurant, crediting a closed-loop cooling design that recirculates the same fluid indefinitely rather than evaporating fresh water to reject heat. The claim, reported June 3, 2026, positions the design as a step-change from conventional facilities that can draw millions of gallons per year.
Executive Summary
The comparison is striking by design: restaurants are among the most water-intensive small businesses people intuitively understand, and equating a hyperscale AI facility to one reframes the water debate around data centers. The engineering behind the claim is real and well understood — closed-loop (or liquid-to-chip, sealed-circuit) cooling fills the system once and rejects heat to the outside air through dry coolers or chillers, eliminating the continuous evaporation that makes traditional cooling towers thirsty.
Why it matters: water has become a genuine siting constraint for AI infrastructure. Communities from the American Southwest to drought-prone regions abroad have pushed back on data center projects over aquifer draw, and utilities increasingly ask about consumptive water use before power. If Microsoft can credibly demonstrate restaurant-scale water budgets at gigawatt-scale campuses, it changes the permitting conversation for the whole industry.
The caveat: the claim as reported applies to new facilities built to the closed-loop design, not Microsoft’s existing fleet, and the reported remarks do not specify how many sites qualify, how the restaurant benchmark is defined, or whether the figure counts the water embedded in the extra electricity that dry heat rejection typically requires.
The Engineering Is Credible — the Accounting Is the Question
Closed-loop cooling is not a moonshot; it is a design choice with known trade-offs. In a conventional data center, cooling towers chill water by evaporating a portion of it — that evaporation is the “consumption” that shows up in the millions-of-gallons figures. A sealed circuit avoids this entirely: coolant is filled at commissioning, circulates across cold plates or heat exchangers at the servers, and dumps heat to ambient air. On-site water use then falls to domestic needs — restrooms, humidification, kitchens — which is plausibly restaurant-scale.
The honest question is boundary-drawing. Site water use is only one ledger. Dry heat rejection generally consumes more electricity than evaporative cooling, especially in hot climates, and most grid electricity has its own water footprint at the power plant. A facility that saves water on site but draws more thermally generated power may shift consumption upstream rather than eliminate it. The reported remarks, as relayed, do not say whether Microsoft’s restaurant comparison is site-only or includes that indirect water. Neither answer would be wrong — but they are very different claims.
Water Is Becoming the Second Currency of AI Siting
For years, the binding constraint on data center development was power: megawatts available, interconnection queue position, substation timelines. Water has quietly become the second gate. Local opposition to AI campuses increasingly centers on aquifer and municipal-supply impacts, and several jurisdictions now require consumptive-use disclosures in permitting. A hyperscaler that can walk into a county hearing with a restaurant-equivalent water budget has a materially easier approval path — and that is worth real money in schedule terms, since permitting delay is often costlier than construction premium.
This creates competitive dynamics beyond Microsoft. If closed-loop designs become the de facto community expectation, operators running evaporative plants may face pressure to retrofit or to defend designs that were unremarkable five years ago. Cooling vendors, dry-cooler manufacturers, and liquid-cooling integrators stand to gain; regions that marketed abundant water as a siting advantage lose a differentiator.
Marketing Benchmarks Deserve the Same Scrutiny as Critics’ Numbers
The water debate around AI has featured loose numbers on all sides — viral estimates of water “per chatbot query” have often rested on contested assumptions, and industry rebuttals have sometimes cherry-picked their best sites. A restaurant comparison is vivid but imprecise: restaurant water use varies enormously by size and type, and the reported claim does not state which benchmark Microsoft used. The fair posture is symmetrical skepticism. Critics’ worst-case figures should be tested against actual metered data; Microsoft’s best-case figure should be tested against fleet-wide averages, third-party verification, and the full indirect footprint. Until per-site water data is published, both the alarm and the reassurance rest partly on trust.
Background
Microsoft is one of the largest builders of AI infrastructure in the world, expanding data center capacity at historic pace to serve AI training and cloud workloads. The company has long publicized environmental commitments — including goals around water stewardship — and in recent years began promoting data center designs that minimize or eliminate evaporative water use, as rising rack densities pushed the industry from air cooling toward liquid cooling.
The water question grew alongside the AI boom: as hyperscale campuses multiplied in water-stressed regions, consumptive use became a flashpoint in local permitting battles and media coverage. The June 2026 remarks land in that context — an industry seeking to prove that AI growth and water stewardship are compatible, before regulators decide the question for it.
Bloomberg published a deep-dive feature, “The Race to Rethink Data Centers for AI’s Power Surge” (May 31, 2026), examining how the electricity demands of artificial intelligence are pushing the industry to redesign data centers from the ground up. The syndicated item carries the headline and framing rather than the full text, but the thesis is clear: AI has turned the data center from a real-estate product into a power-engineering problem, and the industry is racing to catch up.
Executive Summary
The framing matters because it comes from a general-audience financial outlet, not a trade publication. When Bloomberg tells its readership that data centers must be rethought — not incrementally upgraded — it signals that AI infrastructure has become a mainstream capital-markets story. The “race” in the headline is real: operators, chipmakers, cooling vendors, and utilities are all redesigning around a single constraint, the availability and delivery of electric power.
For a decade, data center design evolved slowly because the workload was predictable: web servers, storage, and enterprise applications drawing modest, steady power per rack. AI training and inference clusters broke that model. Racks packed with modern AI accelerators draw many times the power of traditional server racks, concentrate that power in small footprints, and generate heat that air cooling struggles to remove. Every downstream system — electrical distribution, cooling, floor loading, even site selection — inherits that change. That is the ground-up redesign Bloomberg describes.
From Real Estate to Power Engineering
The traditional data center business resembled specialized real estate: build a shell near fiber routes, sell space and a service-level agreement. AI inverts the priority order. The scarce input is no longer land or connectivity but grid capacity — the megawatts a utility can actually deliver to a site, and how soon. In many major markets, interconnection queues (the utility’s waiting list to hook up large new loads) now stretch years, which means the design question starts with “where can we get power?” before anyone draws a floor plan.
That shift changes who holds leverage. Utilities and transmission owners, long treated as background vendors, now effectively gate the industry’s growth rate. Operators that secured power commitments early, or that can bring generation and storage to the site themselves, hold an asset that cannot be quickly replicated. This is why data center announcements increasingly lead with gigawatts rather than square feet.
The Density Problem: Why Air Is No Longer Enough
AI accelerators concentrate enormous computation — and therefore heat — into small spaces. Racks that once drew power in the single-digit kilowatts have given way to AI clusters drawing an order of magnitude more, and air cooling becomes physically impractical at those densities. The industry’s answer is liquid cooling: circulating coolant directly to chips or immersing hardware entirely, because liquids carry heat far more efficiently than air.
Retrofitting liquid cooling into a facility designed for air is expensive and disruptive — new piping, new heat-rejection equipment, reinforced floors, redesigned electrical distribution. That is what makes this a ground-up redesign rather than an upgrade cycle: much of the world’s existing data center stock was simply not built for what AI hardware now requires. New builds can be purpose-designed; legacy facilities face hard choices between costly conversion and serving the workloads they were built for.
Winners, Losers, and the Retrofit Divide
The redesign wave creates clear beneficiaries: liquid-cooling specialists, electrical-equipment manufacturers, builders of on-site generation and battery storage, and operators with new, high-density-capable campuses. Utilities in data-center-heavy regions gain large, creditworthy customers — along with political scrutiny over who pays for grid upgrades and how large loads affect residential rates.
The pressure falls on owners of older facilities and on markets where power is constrained. A bifurcation is plausible: purpose-built AI campuses commanding premium economics, while conventional facilities compete in the lower-growth market for traditional enterprise workloads. For the broader industry, the open question is pacing — whether power delivery, equipment supply chains, and skilled construction labor can scale as fast as AI demand projections assume, and what happens to capital deployed against those projections if demand growth moderates.
What It Means for Buyers of Capacity
Enterprises buying colocation or cloud capacity should read this as a warning about lead times and pricing. When power is the bottleneck, capacity in constrained markets gets scarcer and more expensive, and delivery dates slip to match utility timelines rather than construction schedules. Buyers planning AI deployments should ask providers pointed questions: how much power is actually contracted (not just applied for), what rack densities the facility supports today, and whether liquid cooling is installed or merely on a roadmap. The gap between a marketing deck and an energized megawatt is where AI projects stall.
Background
For most of the 2010s, data centers evolved gradually around predictable enterprise and cloud workloads, with racks drawing modest power and air cooling as the near-universal standard. The generative AI boom that began in late 2022 broke that pattern: training and serving large AI models requires dense clusters of accelerator chips whose power draw and heat output far exceed what conventional facilities were designed to handle. Since then, hyperscalers and data center developers have announced successive waves of AI-focused capacity, and the industry’s public conversation has shifted from square footage to megawatts — with power procurement, cooling technology, and grid constraints emerging as the defining issues of the buildout. Bloomberg’s May 2026 feature places that redesign race in front of a mainstream financial audience.
Data Center Dynamics has published a comparison of the two competing approaches to direct-to-chip liquid cooling — single-phase, where a liquid coolant absorbs heat and stays liquid, and two-phase, where the coolant boils at the chip and carries heat away as vapor — framed around a single question: which is right for AI data centers in 2026?
That the trade press is treating this as a live, unsettled debate is itself the news. As AI accelerators push per-chip power beyond what air can remove, direct-to-chip liquid cooling has moved from exotic to expected, and the industry has not yet converged on which of the two variants will define the next generation of facilities.
Executive Summary
Direct-to-chip liquid cooling puts a cold plate in contact with the processor and runs coolant through it, removing heat far more efficiently than blowing air across a heatsink. Within that category, two architectures are competing. Single-phase systems circulate a liquid — typically treated water or a water-glycol mix — that warms up as it passes over the chip and is cooled elsewhere. Two-phase systems use an engineered dielectric fluid that boils directly on the cold plate; the phase change from liquid to vapor absorbs a large amount of heat at a nearly constant temperature, and the vapor is condensed back to liquid to repeat the cycle.
The choice matters because it is not easily reversible. Coolant chemistry, pressure ratings, manifolds, coolant distribution units, and facility water loops are all designed around one approach or the other. An operator committing today to a multi-hundred-megawatt AI campus is effectively placing a bet on which architecture will best handle the chips of 2028 and beyond — and on which supply chain, service model, and regulatory environment will mature fastest.
The DCD piece lands at the moment this bet has become unavoidable. Air cooling handled decades of servers; single-phase liquid is handling today’s AI racks; the open question is whether tomorrow’s thermal densities force the industry through a second transition to two-phase — or whether single-phase engineering keeps stretching to meet the need.
Why the Question Exists at All
For most of computing history, this debate would have been academic. Air cooling was cheap, well understood, and sufficient. AI training hardware broke that equilibrium: modern accelerators concentrate so much power in so little silicon that the limiting factor is no longer the data center’s chillers but the last few millimeters between the chip surface and the coolant. Direct-to-chip designs attack exactly that bottleneck, which is why they have become the default assumption for new AI builds.
Single-phase direct-to-chip won the first round largely on familiarity. Water-based cooling loops are a known quantity — data center engineers, plumbers, and component suppliers have decades of experience with pumps, valves, and leak management for liquid water. Two-phase systems promise something physically compelling in exchange for novelty: boiling a fluid absorbs latent heat, meaning the coolant can soak up substantially more energy without a large temperature rise, and it does so uniformly across the hottest parts of the chip.
The Engineering Trade-Offs, Plainly Stated
Single-phase’s strengths are operational. The fluids are inexpensive and benign, the components are commodity, leaks are messy but manageable, and the industry’s existing skills transfer directly. Its weakness is headroom: as chips run hotter, single-phase designs must push more liquid, faster, through smaller channels, and must manage the temperature gradient across the cold plate — the chip’s inlet edge runs cooler than its outlet edge, which complicates thermal design as power climbs.
Two-phase inverts that profile. Boiling heat transfer offers high performance and near-isothermal operation — the whole cold plate sits close to the fluid’s boiling point — which is attractive precisely where single-phase strains. But the costs are real: engineered dielectric fluids are far more expensive than water, systems must manage vapor and pressure rather than simple liquid flow, servicing a sealed two-phase loop is a different discipline, and several candidate fluids belong to chemical families (such as PFAS-related compounds) facing regulatory scrutiny in major markets. A technically superior heat-transfer mechanism does not automatically win if its fluid supply or compliance picture is uncertain.
Who Wins and Loses on Each Path
If single-phase continues to stretch, the winners are incumbents: established cooling vendors, existing supply chains, and operators who have already deployed water-based loops and want continuity. Chip designers absorb more of the burden, engineering packages and cold plates to live within single-phase limits. If two-phase becomes necessary, the advantage shifts toward specialist fluid and systems companies, and toward operators willing to build new competencies early — with the corresponding risk of backing immature technology.
There is also a middle path worth naming: hybrid facilities, where single-phase handles the bulk of the load and two-phase (or other advanced techniques) is reserved for the hottest components or highest-density halls. Many operators will likely hedge this way rather than commit wholesale, which suggests the 2026 answer to “which is right?” may genuinely be “both, in different places” — an unsatisfying but rational outcome for an industry making thirty-year infrastructure bets on three-year chip roadmaps.
What This Means for the Broader Market
The cooling decision cascades outward. Coolant choice affects how much heat a facility can reject to the outside world and at what temperature, which shapes heat-reuse opportunities and water consumption. It affects colocation providers, who must decide which architecture to offer tenants whose hardware they do not control. And it affects the retrofit market: the vast installed base of air-cooled data centers faces different conversion economics depending on which liquid architecture prevails. Standardization efforts — common connectors, fluid specifications, and safety practices — will matter as much as raw thermal performance in determining which camp scales fastest.
Background
Data centers spent decades cooled almost entirely by air: chilled air pushed through raised floors and hot aisles, with per-rack power low enough that fans and heatsinks sufficed. The AI buildout broke that model. Training clusters pack accelerators drawing unprecedented power into dense racks, pushing the industry through its biggest thermal transition since the mainframe era — first to rear-door heat exchangers and now to liquid brought directly to the chip.
Data Center Dynamics, the publication behind this comparison, is a long-running trade outlet covering data center design and operations. That its editorial attention has moved from whether to liquid-cool to which liquid architecture to choose reflects how quickly direct-to-chip cooling has become the baseline assumption for AI infrastructure — and how much unresolved engineering debate still sits beneath that baseline.
On May 28, 2026, NVIDIA published a blog post titled AI Factories: The New Infrastructure of Intelligence, arguing that facilities purpose-built to train and serve large AI models constitute a new class of infrastructure rather than an extension of the traditional data center.
The post is a positioning piece, not an announcement of a specific project, customer, or product SKU. It reinforces a term NVIDIA executives have used with increasing frequency over the past two years as hyperscalers and neoclouds stand up gigawatt-scale GPU campuses.
Executive Summary
NVIDIA’s message is straightforward: buildings full of GPUs that ingest data and output tokens, weights, and inference responses look and behave differently enough from general-purpose data centers to deserve their own name. The company’s implicit argument is that treating these sites as ordinary colocation halls understates the electrical, thermal, network, and financial redesign they require.
Why it matters: language shapes procurement. If buyers, financiers, and regulators accept ‘AI factory’ as a distinct category, it changes how sites are permitted, how power contracts are written, how depreciation is modeled, and which vendors are considered incumbents. NVIDIA benefits when the category is defined around dense GPU clusters, high-bandwidth fabrics, and liquid cooling — all areas where its stack is already assumed.
For operators and enterprise buyers, the practical question is whether the label describes something genuinely new or repackages a trajectory the industry was already on: higher rack densities, direct-to-chip liquid cooling, campus-scale power procurement, and tighter compute-storage-network integration.
Why NVIDIA Wants a New Category
Categories are strategic. When cloud computing was rebranded from ‘hosted servers,’ it justified a decade of premium pricing and shifted procurement out of IT and into finance and operations. NVIDIA has commercial reasons to define AI infrastructure in terms that center accelerated compute — the more the industry treats an ‘AI factory’ as fundamentally GPU-shaped, the harder it is for CPU-first, ASIC-first, or non-NVIDIA-accelerator architectures to be considered the default. This is not dishonest; it is positioning, and buyers should read it as such.
The framing also helps NVIDIA’s customers. Hyperscalers and specialized GPU cloud providers raising tens of billions in debt and equity benefit from a narrative that these are not commodity data centers competing on price per kilowatt, but capital assets producing a scarce good — intelligence — at industrial scale. Factories, unlike data centers, are supposed to have output curves, unit economics, and productive capacity that justifies their capex.
What Is Actually Different — And What Is Not
The technical case for a distinct category rests on real changes. Training clusters routinely exceed 100 kilowatts per rack, versus roughly 10-20 kW for a typical enterprise hall, forcing liquid cooling rather than air. Network topology is dominated by east-west traffic between GPUs on high-bandwidth fabrics, not north-south client traffic. Power draw is spiky and correlated across thousands of chips, which strains grid interconnections in ways general-purpose workloads do not. Site selection is increasingly driven by available generation capacity rather than proximity to users, since training is latency-tolerant.
What is not obviously new is the underlying building. A well-run modern data center campus with high-density zones, on-site substations, and liquid loops can host these workloads, and many do. The ‘factory’ language risks obscuring a continuum: most operators are retrofitting and expanding existing sites rather than inventing a new asset class from scratch. Whether that continuum deserves a new noun is more a marketing question than an engineering one.
Winners, Losers, and Who Is Watching
Beneficiaries of the framing include NVIDIA and its close ecosystem — networking silicon, liquid cooling vendors, and reference-design integrators — plus GPU cloud specialists whose entire pitch is that they are purpose-built rather than repurposed. Incumbent colocation providers face a subtler pressure: they must show that their halls can be reconfigured to the same density and efficiency, or accept being characterized as legacy.
Regulators, utilities, and communities are the audience that matters most for the label’s staying power. Calling a facility a factory invites questions about industrial siting, emissions accounting, job creation per megawatt, and grid impact that data centers have historically been able to sidestep. NVIDIA’s category may prove more consequential in permitting hearings than in procurement meetings.
Background
NVIDIA is the dominant supplier of GPUs and associated networking used to train and serve large AI models, and over the past three years its executives have repeatedly framed AI infrastructure as a new industrial category. The ‘AI factory’ language has appeared in keynotes, investor communications, and partner announcements, and this blog post consolidates that framing.
The backdrop is a global build-out of purpose-built AI campuses by hyperscalers, sovereign AI initiatives, and specialized GPU cloud providers, funded by tens of billions in equity and debt. Site selection has increasingly shifted toward regions with available power generation, and the industry is in the middle of a transition from air to liquid cooling and from ethernet-centric to specialized high-bandwidth network fabrics.
Modine Manufacturing has signed a cooling solutions agreement valued at $4 billion with a hyperscale data center customer, as reported by BizTimes Milwaukee on May 27, 2026. The agreement centers on direct-to-chip liquid cooling — technology that removes heat from processors through cold plates mounted directly on the silicon — and ranks among the largest single cooling-infrastructure commitments ever disclosed.
The customer was not named in the report, and details such as contract duration, delivery schedule, and the split between hardware, installation, and services were not disclosed.
Executive Summary
The announcement matters for two reasons. First, the sheer size: $4 billion for cooling alone would have been implausible only a few years ago, when cooling was a modest slice of data center capital budgets dominated by air-handling equipment. A commitment of this scale signals that liquid cooling has become a first-order line item in hyperscale AI buildouts, driven by processor power densities that air cooling cannot economically serve.
Second, the counterparty structure: a single hyperscale customer writing a multi-billion-dollar cooling commitment suggests the largest cloud and AI operators are now locking up thermal-management supply the way they already lock up power, land, and chips. For Modine — a century-old thermal-management company headquartered in Racine, Wisconsin — an agreement of this magnitude is potentially transformative relative to its historical revenue base, though how the value converts to recognized revenue over time is not yet clear from the report.
Cooling Graduates From Line Item to Mega-Contract
Direct-to-chip cooling circulates liquid coolant through cold plates that sit directly on top of processors, carrying heat away far more efficiently than blowing chilled air across server racks. The technology exists because modern AI accelerators draw so much power — and concentrate it in so little space — that traditional air cooling hits physical and economic limits. As rack densities climb from tens of kilowatts toward 100 kilowatts and beyond, liquid cooling shifts from an exotic option to a requirement.
A $4 billion commitment to a single cooling vendor is the clearest evidence yet of that shift. Hyperscalers historically procured cooling equipment project by project, from a fragmented field of suppliers. Consolidating that spend into one long-horizon agreement mirrors how they already contract for power and semiconductors: secure capacity early, at scale, before competitors do. If that procurement pattern spreads, the cooling industry’s competitive dynamics change — scale, manufacturing capacity, and balance-sheet strength start to matter as much as thermal engineering.
What the Deal Could Mean for Modine
Modine is best known as a legacy thermal-management manufacturer — its roots are in vehicle radiators — that has spent recent years repositioning toward data center cooling through its climate-solutions business and its Airedale data center cooling brand. A $4 billion agreement would be large relative to what mid-cap industrial suppliers typically book across multiple years, which is precisely why the announcement drew attention beyond the trade press.
The caveat is that headline contract values and recognized revenue are different things. The report does not say whether the $4 billion represents a firm purchase obligation, a framework agreement with volume expectations, or a ceiling contingent on the customer’s buildout pace. Investors have learned from other AI-infrastructure announcements that multi-year framework deals can be revised as deployment schedules shift. Until Modine discloses the structure, the number is best read as a statement of intended scale rather than booked backlog.
An Unnamed Customer and the Concentration Question
Hyperscale operators routinely require anonymity from suppliers, so the customer’s absence from the report is normal practice, not a red flag. But it leaves open a question that matters for assessing the deal: customer concentration. A supplier whose order book is dominated by one buyer gains scale but inherits that buyer’s capital-spending cycle. If the customer slows its AI data center buildout — for reasons ranging from power availability to shifts in AI demand — the supplier feels it directly.
The flip side is validation. Hyperscalers qualify cooling vendors through demanding technical and reliability reviews, because a cooling failure in a liquid-cooled AI cluster can take down hardware worth far more than the cooling system itself. Winning a commitment of this size implies Modine cleared that bar at scale, which itself is a competitive signal to the rest of the market.
The Competitive Ripple Across the Cooling Market
The direct-to-chip market has been contested by a mix of large incumbents and specialists, and a deal of this size resets expectations for what winning looks like. Rivals will face pressure to demonstrate comparable manufacturing capacity and to pursue their own anchor agreements with major operators. For buyers below hyperscale size — enterprises and smaller cloud providers — the concern runs the other way: if the biggest customers lock up vendor capacity, lead times and pricing for everyone else could tighten.
There is also an upstream effect. Direct-to-chip systems depend on coolant distribution units, quick-disconnect fittings, cold plates, and pumps — components with their own supply chains. A $4 billion program implies significant component demand over its life, which tends to pull investment into that supplier tier. The unanswered question is timing: without a disclosed delivery schedule, it is impossible to gauge how quickly that demand arrives.
Background
Modine Manufacturing is a Wisconsin-based thermal-management company whose history stretches back over a century, beginning with radiators for early automobiles. Like several legacy industrial firms, it has pivoted toward data center cooling as that market’s growth outpaced its traditional vehicle business, building out a climate-solutions portfolio that includes the Airedale data center cooling brand and, more recently, liquid-cooling capabilities aimed at AI workloads.
The backdrop is a structural shift in data center design. The AI buildout that accelerated from 2023 onward pushed rack power densities beyond what air cooling can serve, making liquid cooling — and direct-to-chip systems in particular — one of the fastest-growing segments of data center infrastructure spending.
Engineering trade publication Electronics360 published an analysis on May 24, 2026 arguing that direct-to-chip (D2C) liquid cooling — circulating coolant through cold plates mounted directly on processors — has crossed from a design option to a practical requirement, driven by AI accelerator chips whose power draw has reached the multi-kilowatt range per device.
The piece frames this as the end of an era: air cooling, the default thermal strategy for data centers since the industry’s beginning, can no longer keep pace with the heat that flagship AI silicon produces in the small area of a single chip package.
Executive Summary
The core claim is thermodynamic rather than commercial: individual AI processors now dissipate thousands of watts each, and moving that much heat out of a dense rack with air alone requires airflow volumes and temperature differentials that become impractical or impossible at the densities AI clusters demand. Direct-to-chip liquid cooling, which places a liquid-filled cold plate against the chip itself, removes heat far more efficiently because liquids carry heat orders of magnitude better than air.
Why it matters: if D2C is genuinely mandatory rather than optional, every layer of the data-center stack changes — facility design, plumbing, power distribution, rack architecture, maintenance skills, and capital budgets. Operators of existing air-cooled facilities face retrofit decisions, and new builds are being designed liquid-first. For an industry that standardized on air handling for decades, this is a foundational transition, not an incremental upgrade.
Physics Ended the Debate Before the Market Did
Air cooling persisted as the default not because it was elegant but because it was cheap, simple, and universally understood. Its limitation is fundamental: air is a poor heat conductor, so cooling a hotter chip means moving more air, faster, across larger heatsinks. As AI accelerators pushed past one kilowatt per device — with roadmaps pointing well beyond — the heat concentrated in a few square centimeters of silicon began to exceed what any realistic airflow can absorb. Water and engineered coolants transfer heat dramatically more effectively, which is why cold plates bolted directly onto the chip package have become the pragmatic answer.
The word ‘mandatory’ in the source’s framing is worth taking seriously but precisely. Air cooling is not disappearing from data centers generally — the vast installed base of conventional enterprise and cloud workloads runs at rack densities air handles fine. The mandate applies to the frontier: dense AI training and inference clusters built around multi-kilowatt accelerators. That distinction matters for anyone budgeting a transition.
The Retrofit Question Splits the Market
Liquid-first design is straightforward in a new build: coolant distribution units, manifolds, leak detection, and higher floor loading are engineered in from day one. Retrofitting an existing air-cooled facility is harder. Piping must be routed through spaces never designed for it, water supply and heat-rejection capacity must be added, and operations teams must learn to manage a system where a leak — rare but nonzero — sits inches from expensive silicon.
This creates a divergence in asset value across the industry. Facilities that can economically accept liquid cooling — because of their power capacity, structure, and location — become more valuable as AI demand grows. Older facilities that cannot may be relegated to lower-density workloads. Colocation providers, hyperscalers, and enterprise operators are all making that assessment now, and the answers will shape which real estate wins the AI buildout.
A New Supply Chain Rises Around the Cold Plate
A shift of this scale redraws the vendor landscape. Demand moves toward cold plates, coolant distribution units, quick-disconnect fittings, dielectric and water-based coolants, leak-detection systems, and rear-door or facility-level heat exchangers — categories that were niche a few years ago. Established thermal-management and precision-cooling vendors are competing with newer specialists, and chip and server makers increasingly ship liquid-ready designs, effectively deciding the question for their customers.
There is also an efficiency dividend. Because liquid captures heat at the source, less energy is spent on fans and air handling, and the warm coolant leaves at temperatures useful for heat reuse in some settings. For operators facing scrutiny over data-center energy consumption, D2C offers a genuine efficiency story — though it introduces its own considerations around water use and coolant handling that deserve equally honest accounting.
Background
For most of computing history, data centers were cooled the same way: chilled air pushed through raised floors or ducts, across finned metal heatsinks, and back to air-handling units. That model worked because individual chips drew tens or hundreds of watts. The AI era broke the assumption — training and running large models rewards packing the most powerful accelerators as densely as possible, and each generation of AI silicon has raised per-chip power substantially, crossing the kilowatt mark and continuing upward.
Liquid cooling itself is not new; mainframes and supercomputers used water cooling decades ago before commodity air-cooled servers displaced them on cost. What has changed is that the physics that once made liquid cooling a supercomputing niche now applies to mainstream AI infrastructure, pulling a once-specialist discipline back to the center of data-center design.
Source: Multi-kilowatt chips make D2C cooling mandatory — Electronics360 analysis (May 24, 2026) on why multi-kilowatt AI processors are forcing data centers from air cooling to direct-to-chip liquid cooling.
An analysis published by Data Center Frontier on May 22, 2026 argues that the rise of AI workloads is reshaping how data center operators define and manage risk, moving the conversation beyond the long-standing focus on uptime toward a broader notion of resilience that spans power, cooling, network, and workload recovery.
Executive Summary
The piece reframes a debate that has quietly been building for several years. For decades, the data center industry benchmarked itself on uptime — the percentage of time facilities remained available, typically measured against Uptime Institute tier definitions. AI training and inference workloads, with their concentrated power draw, thermal density, and tightly coupled cluster behavior, expose the limits of that single metric.
Why it matters: buyers of colocation and cloud capacity have historically negotiated on service-level agreements built around availability. If the operative risk is now cluster-level disruption, cooling excursions, or grid interaction rather than isolated component failure, the contracts, insurance, and design standards that underpin the industry will need to evolve alongside the hardware.
Uptime Was Built for a Different Workload
The uptime-first mindset was calibrated for enterprise and early cloud workloads: many independent servers, stateless front ends, and applications that tolerated the loss of a node without disrupting the service. A five-nines facility (99.999 percent availability, roughly five minutes of downtime a year) was a defensible proxy for customer experience because software above it was designed to route around small failures.
AI training clusters behave differently. A single training job may span thousands of GPUs (graphics processing units, the specialized chips that do the heavy math for AI models) synchronized on every step. A brief power event, a cooling excursion, or a network partition can force a checkpoint restart that costs hours of compute and, at current GPU rental rates, meaningful money. Availability at the facility level says little about whether the job actually finishes.
Resilience Is a Wider Surface
Resilience, as the source frames it, is a superset of uptime. It includes how quickly a site can ride through a grid disturbance, whether liquid cooling loops degrade gracefully under partial failure, how the network fabric behaves when a spine switch drops, and how workloads are checkpointed so that a disruption does not erase a day of training. Each of those is a distinct engineering discipline, and each has its own vendors, standards, and blind spots.
That widening surface also expands who bears the risk. Uptime SLAs put the operator on the hook for a narrow, well-defined failure mode. Resilience, by contrast, is a shared problem: the utility, the operator, the cooling vendor, the network provider, and the customer’s own software all shape whether a workload survives a bad afternoon. Contract structures have not caught up.
What Changes for Buyers and Operators
For operators, the practical implication is that design margins that looked conservative in a CPU-era facility can look thin under AI density. Rack power draws that used to sit in the 5 to 15 kilowatt range are now routinely quoted in the tens to over a hundred kilowatts per rack for GPU deployments, which stresses power distribution, cooling headroom, and the assumptions baked into concurrent maintainability. Retrofitting a legacy hall is not always cheaper than greenfield.
For buyers, the negotiation should widen. Beyond the availability guarantee, questions worth asking include how the site responds to grid frequency events, how cooling redundancy is validated under load rather than at commissioning, what the network’s failure domains look like, and whether the operator can produce evidence — not just design documents — of resilience under stress. None of this makes uptime irrelevant; it just makes uptime insufficient.
Background
The data center industry has organized itself for decades around the Uptime Institute’s tier system, which rates facilities from Tier I to Tier IV based on redundancy and concurrent maintainability. That framework, alongside vendor SLAs measured in nines of availability, became the common vocabulary for negotiating colocation and cloud contracts.
The rapid buildout of AI training and inference capacity from roughly 2023 onward has introduced rack densities, power profiles, and workload behaviors that the tier framework was not designed around. Industry publications including Data Center Frontier have been tracking the resulting rethink of design standards, power procurement, and cooling architecture.
NVIDIA reported fiscal first-quarter results that beat Wall Street expectations, according to a May 20, 2026 report from Yahoo Finance, with the ramp of its Blackwell GPU platform and continued strength in its data center business cited as the drivers. The data center segment — the chips, systems, and networking sold to cloud providers and enterprises building AI capacity — remains the company’s growth engine.
Executive Summary
The headline is short but the signal is clear: as of mid-2026, demand for AI compute has not slowed enough to dent the results of the industry’s dominant supplier. NVIDIA’s quarterly reports have become a de facto barometer for the entire AI infrastructure economy, because nearly every hyperscaler, cloud provider, and AI lab routes a large share of its capital spending through NVIDIA’s data center products. A beat attributed to the Blackwell ramp means the newest generation of accelerators is shipping in volume and being absorbed by buyers.
For the infrastructure industry — data center operators, power providers, network carriers, and cooling vendors — this matters more than the stock move. Every Blackwell system that ships needs a rack to sit in, megawatts to run on, liquid cooling to survive, and high-bandwidth connectivity to be useful. Strong GPU shipments today are a leading indicator of facility demand for the next several quarters.
Why One Company’s Earnings Read as an Industry Health Check
NVIDIA occupies an unusual position: it supplies the scarcest input in the AI buildout, so its revenue is effectively a meter on how much money the world’s largest technology companies are actually spending — not merely announcing — on AI capacity. Press releases about future data center campuses can slip or shrink; recognized GPU revenue cannot. When the data center segment beats expectations, it means purchase orders were placed, systems were built, and customers took delivery.
That is why analysts treat these reports as a proxy for hyperscaler capital expenditure. The persistent worry in this cycle has been a gap between announced AI ambitions and realized spending. A quarter driven by Blackwell — the successor architecture to Hopper, designed for large-scale AI training and inference — suggests buyers are not just sustaining spend but migrating to the newest, most power-dense generation.
The Blackwell Ramp Is a Facilities Story, Not Just a Chip Story
Each GPU generation raises the bar on what a data center must provide. Blackwell-class systems are typically deployed in dense racks that draw far more power than traditional enterprise IT and generally require liquid cooling rather than air. A successful ramp therefore implies a parallel ramp in facilities engineered for high-density, liquid-cooled deployments — and it pressures older facilities that cannot economically retrofit.
The winners in that shift extend well beyond NVIDIA: colocation and wholesale data center operators with available power, utilities and on-site generation providers, cooling-equipment manufacturers, and the optical and electrical networking suppliers that stitch GPU clusters together. The constraint has increasingly moved from chip supply to megawatts and grid interconnection queues — meaning the bottleneck NVIDIA’s customers face next is often land, power, and time, not silicon.
What a Beat Does and Does Not Prove
A single quarter’s beat confirms present demand; it does not settle the debate about durability. Skeptics of the AI buildout argue that spending is concentrated among a handful of hyperscalers and well-funded AI labs, and that returns on AI investment must eventually justify the capital outlay. Supporters counter that inference — running AI models in production, not just training them — is broadening the buyer base. The headline alone does not adjudicate this; it tells us the engine was still pulling as of the April-ending quarter.
It is also worth remembering that expectations themselves are a moving target. “Beat” means results exceeded analyst consensus, and consensus for NVIDIA has been recalibrated upward repeatedly for over two years. The more durable takeaway for infrastructure planners is directional: the newest platform is ramping, and buyers are absorbing it.
Background
NVIDIA began as a graphics-chip company for PC gaming, but its GPUs proved ideal for the parallel math behind modern AI, and since late 2022 the generative-AI boom has transformed it into the central supplier of the AI buildout and one of the world’s most valuable companies. Its data center segment now dwarfs its original gaming business, and its quarterly reports are watched as a barometer for AI capital spending across the technology industry.
The Blackwell platform, announced in 2024 as the successor to the Hopper generation, is deployed in dense, liquid-cooled rack systems by cloud providers and AI companies. Each generational transition raises the power and cooling requirements on the data centers that host these systems, tying NVIDIA’s product cycle directly to the fortunes of the facilities, power, and connectivity industries.
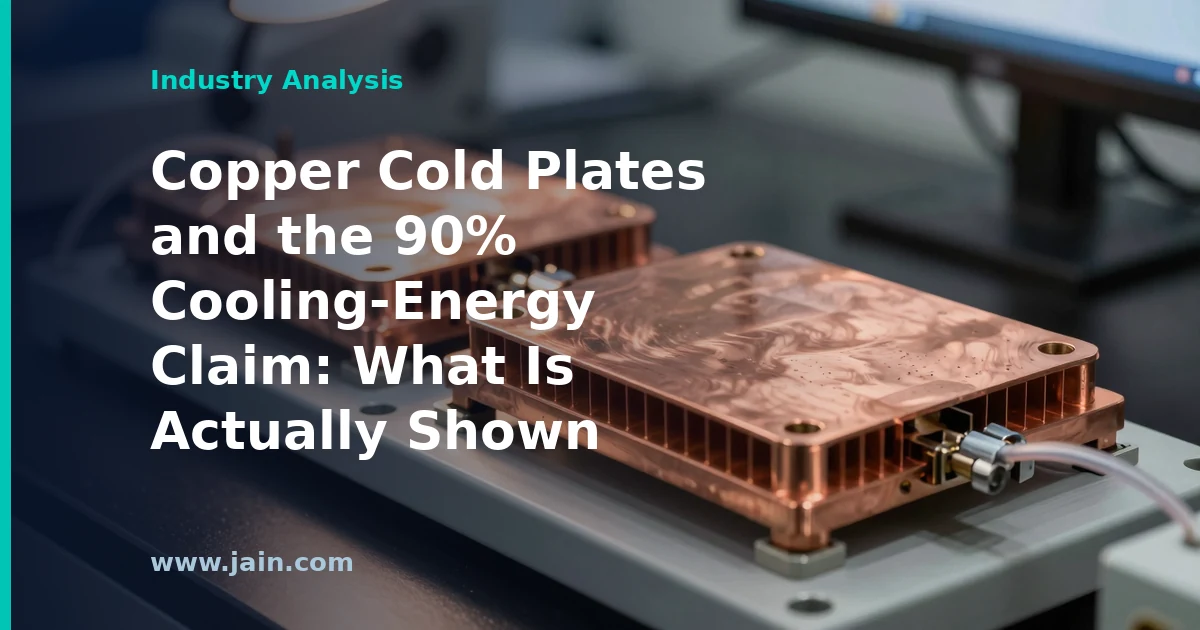
A report published May 19, 2026 by New Atlas describes a copper cold-plate cooling design that, its developers say, could slash data-center cooling energy use by as much as 90%. Cold plates are metal blocks that sit directly on hot chips and carry heat away in circulating liquid, and they are already the workhorse of liquid cooling for AI servers.
The syndicated listing carries the headline claim but few technical specifics, so the central question for operators is what baseline the 90% figure is measured against and how far the design is from production racks.
Executive Summary
The announcement lands in the middle of the data-center industry’s most pressing operational problem: heat. As AI accelerators push individual chips past the point where moving air can cool them, operators are converting to direct liquid cooling, in which coolant is piped to a copper plate mounted on each processor. Cooling can consume a substantial share of a facility’s total power, so a design that meaningfully cuts that overhead would translate directly into more of a site’s grid connection being available for compute — the scarcest resource in the industry right now.
That is why a 90% reduction claim deserves attention, and also why it deserves scrutiny. Laboratory cooling advances routinely post dramatic percentage improvements against narrow baselines — often legacy air cooling rather than the modern liquid systems they would actually compete with. The report as syndicated does not settle which comparison is being made, what workloads were tested, or what the path to manufacturing looks like.
Our read: the direction of the work is squarely aligned with where the industry is going, but the headline number should be treated as a research claim pending the details — test conditions, baseline, and durability data — that determine whether it survives contact with a production rack.
Why Cooling Energy Is the Prize
Every watt a data center spends on cooling is a watt it cannot sell as compute. The industry measures this with PUE (power usage effectiveness), the ratio of total facility power to IT power; cooling is typically the largest contributor to the overhead above 1.0. With utilities quoting multi-year waits for large new grid connections, reducing cooling energy is one of the few ways an operator can add sellable capacity inside an existing power envelope.
AI has sharpened the problem. Modern accelerators dissipate far more heat per chip than the servers most air-cooled facilities were designed around, and rack densities have climbed to the point where liquid cooling is no longer optional for leading-edge deployments. Any credible improvement in how efficiently heat moves from silicon to the outside world therefore has a direct, monetizable value — which is exactly why cooling claims also attract inflated framing.
What a Cold Plate Does, and Where 90% Could Come From
A cold plate is conceptually simple: a copper block with internal channels, clamped to a chip, with liquid flowing through it. Copper is used because it conducts heat exceptionally well. The engineering is in the internal geometry — how the channels are shaped determines how much heat the plate extracts per unit of coolant flow, and how much pumping energy is needed to push liquid through it.
Large system-level energy savings in cooling generally come from one of a few places: extracting heat more effectively so pumps and fans work less; running coolant at warmer temperatures so facilities need little or no energy-hungry mechanical chilling; or exploiting phase change, where evaporating liquid absorbs far more heat than warming it does. The report does not specify which mechanisms this design relies on, and the answer matters — a plate that enables warm-water operation saves energy at the facility level, while one that merely improves plate-level performance saves much less in practice.
The Baseline Question
The most important unstated detail is what the 90% figure is measured against. Compared with a legacy air-cooled facility using mechanical chillers, a well-executed modern liquid-cooling system can already cut cooling energy dramatically — so a new design showing 90% savings against air cooling would be roughly matching the state of the art, not leapfrogging it. A 90% saving against current cold-plate systems would be a genuinely major result, but a far more demanding claim requiring correspondingly strong evidence.
This is not a criticism unique to this announcement; it is the standard failure mode of cooling-technology communication. Percentage claims are only as meaningful as their denominators, and syndicated coverage frequently drops the denominator. Buyers evaluating any such technology should ask for the comparison system, the coolant supply temperature, the heat load tested, and the pumping power included in the accounting.
From Lab Bench to Production Rack
Even a validated design faces a long road to deployment. Cold plates must be manufactured at volume and consistent quality, qualified against leaks over multi-year lifetimes, integrated with server vendors’ thermal designs, and supported by the manifolds, coolant-distribution units, and facility water loops that make up a complete cooling chain. Hyperscale operators typically require extended reliability testing before new thermal hardware touches revenue-generating silicon.
The realistic near-term significance of research like this is therefore directional: it signals continued headroom in cold-plate engineering at exactly the moment the market is standardizing on the technology. Incumbent cooling suppliers, server OEMs, and chipmakers all have active cold-plate programs, so novel designs tend to reach the market through licensing or acquisition rather than as standalone products. For operators, the practical takeaway is that cooling efficiency is still improving quickly enough to factor into facility designs with multi-decade lifetimes.
Background
Data-center cooling has moved through distinct eras: raised-floor air cooling with room-scale chillers, then contained hot/cold aisles and free-air economization, and now direct liquid cooling as AI chips exceed what air can handle. Cold plates — liquid-cooled copper blocks on each processor — have shifted in just a few years from a niche high-performance-computing technique to the default for new AI capacity, alongside alternatives such as immersion cooling, which submerges entire servers in dielectric fluid.
Because cooling is the largest controllable overhead in facility power, and because grid capacity has become the binding constraint on data-center growth, cooling-efficiency research now attracts intense industry and investor attention — along with a steady stream of dramatic percentage claims that reward careful reading of their baselines.