Infrastructure investment firm I Squared Capital announced on May 26, 2026 the launch of a new United States data center platform focused on AI inference and edge colocation, backed by a $1 billion capital commitment. The announcement, distributed via Business Wire, positions the platform to serve the fast-growing market for running trained AI models close to users, rather than the massive centralized campuses where those models are built.
Executive Summary
I Squared Capital, a global infrastructure investor with a track record of building digital-infrastructure platforms from the ground up, is committing $1 billion to a US platform aimed at two intertwined markets: AI inference — the compute that answers queries after a model is trained — and edge colocation, meaning smaller data centers positioned in or near population centers where enterprises can rent space and power.
The bet matters because it stakes real capital on a specific view of where the AI buildout goes next. Most headline-grabbing investment to date has chased hyperscale training campuses measured in hundreds of megawatts, sited wherever cheap power exists. An inference-and-edge thesis argues the next wave of demand is distributed: many smaller facilities, closer to users, optimized for low latency and steady utilization rather than raw scale. If that view is right, data-center value will spread across many US metros instead of concentrating in a handful of power-rich regions.
Inference Is a Different Business Than Training
Training a large AI model is a batch job: it can run anywhere power is cheap, and users never interact with it directly. Inference is a service: every chatbot reply, search summary, and copilot suggestion is an inference call, and its economics are governed by latency (how fast a response travels to the user), utilization, and cost per query. That pushes inference capacity toward network-dense locations near people — the historic strength of colocation and edge facilities rather than remote gigawatt campuses.
By naming inference and edge together, I Squared is effectively arguing that the AI market is maturing from build-the-model to serve-the-model. Industry observers have long noted that if AI adoption follows the path of earlier computing waves, ongoing inference spending should eventually dwarf one-time training spending. A platform purpose-built for that phase is a bet on the durable, recurring part of the AI stack.
A Contrarian Read on Data-Center Geography
The prevailing US buildout has concentrated in a few power-abundant corridors — the kind of places where a utility can pledge hundreds of megawatts. Edge colocation inverts that logic: smaller footprints, more sites, and proximity to enterprises and consumers in secondary metros. The trade-off is that edge sites face urban land costs, tighter permitting, and constrained grid connections, but they can command premium pricing for low-latency capacity and are less exposed to the single-market risks of mega-campuses.
For enterprise buyers, a credible national inference-and-edge platform would offer an alternative to shipping every AI workload to a distant hyperscale region — relevant for latency-sensitive applications, data-residency requirements, and hybrid architectures that keep proprietary data close to home. For incumbent colocation providers, it signals a well-capitalized new competitor targeting exactly the niche where regional operators have historically differentiated.
What $1 Billion Buys — and What It Doesn’t
A $1 billion commitment is serious money and, at the same time, a measured entry. In today’s market, a single large hyperscale campus can absorb several billion dollars, so this commitment points toward a portfolio of smaller facilities rather than one flagship — consistent with the edge thesis. Infrastructure funds also routinely amplify equity commitments with project-level debt, so the platform’s ultimate buildout capacity could be a multiple of the headline figure, though the release itself does not say so.
I Squared has used the platform playbook before in digital infrastructure, assembling operating companies around a thesis and scaling them through acquisition and greenfield development. The open question is execution: inference-optimized facilities still need power, cooling for dense GPU racks, and — most importantly — tenants. The announcement describes a commitment and a strategy; converting that into leased, revenue-generating megawatts is a multi-year undertaking in a market where skilled operators, grid interconnection queues, and equipment lead times are all under strain.
Risks: The Edge-Inference Thesis Is Not Yet Settled
It is worth stating plainly that the distributed-inference future this platform anticipates is a forecast, not a fact. Today, a large share of inference still runs in the same hyperscale regions as training, because cloud providers concentrate their GPU fleets there and many applications tolerate tens of milliseconds of extra latency. If model efficiency improves faster than demand grows, or if hyperscalers simply extend their own regions closer to users, the addressable market for independent edge inference capacity could prove smaller than proponents expect.
None of that makes the bet unreasonable — infrastructure investing is precisely about positioning capital ahead of demand. But buyers and competitors evaluating this announcement should weigh that the release, as reported, substantiates a commitment and a strategy rather than contracted customers or operating assets.
Background
I Squared Capital is an independent infrastructure investment firm founded in 2012 and headquartered in Miami, managing capital across energy, utilities, transport, and digital infrastructure worldwide. In digital infrastructure specifically, the firm has favored a platform model — creating or acquiring an operating company around an investment thesis, then scaling it through greenfield development and bolt-on acquisitions, including prior edge data-center investments in Europe.
The announcement lands amid an unprecedented US data-center expansion driven by AI. Most capital to date has flowed to hyperscale training campuses in power-rich regions, but a growing school of thought holds that as AI applications reach mass adoption, the serving side — inference — will demand distributed, network-proximate capacity, reviving the strategic value of edge and metro colocation.
Argonne National Laboratory announced on May 26, 2026 that it has launched what it describes as the first large-scale artificial intelligence inference service for open science. In plain terms, the U.S. Department of Energy lab is now operating a shared service that lets researchers run trained AI models on demand — the way commercial AI platforms serve their users — rather than reserving supercomputer time for each job.
The announcement, published by Argonne (anl.gov), positions the service as a resource for the open-science community, the network of publicly funded researchers whose methods and results are meant to be broadly shared.
Executive Summary
The significance here is less about any single piece of hardware and more about an operating model crossing an institutional boundary. Hyperscalers — the large cloud and AI companies — long ago mastered inference serving: keeping trained models resident and answering requests in real time, at scale, for many simultaneous users. National laboratories, by contrast, have historically run batch systems, where scientists queue jobs and wait their turn. Argonne is now claiming a first: bringing that always-on, request-driven serving model to open science at large scale.
If the service works as described, it changes the day-to-day texture of AI-assisted research. Scientists could embed model calls directly into instruments, workflows, and analysis pipelines instead of scheduling supercomputer allocations for every experiment. It also signals that DOE laboratories intend to be operators of AI infrastructure in their own right, not just consumers of commercial APIs — a stance with real implications for data governance, cost, and scientific reproducibility.
The public announcement is short on specifics, however. As of the release date, key details — the hardware behind the service, which models it serves, who qualifies for access, and how capacity is allocated — are not spelled out in the source available to us, and we flag those gaps below.
From Batch Queues to On-Demand Serving
Supercomputing centers were built around a simple economic logic: the machine is the scarce asset, so users line up for it. Jobs are submitted to a scheduler, wait in a queue, run to completion, and release the hardware. That model suits training runs and simulations that take hours or days. It suits inference badly. Inference — using an already-trained model to answer a question, label an image, or steer an experiment — is bursty, latency-sensitive, and interactive. A researcher who wants a model’s answer in two seconds cannot wait two hours in a queue.
Standing up a dedicated inference service means Argonne is carving out capacity that stays warm and answers requests continuously, which is a genuine architectural and operational departure for a national lab. It requires the disciplines hyperscalers developed over a decade: request routing, autoscaling, multi-tenancy, uptime engineering. The claim of being ‘first at large scale’ in the open-science context is Argonne’s framing, but the underlying shift it describes — labs adopting service-oriented AI operations — is real and consequential.
Why Labs Want Their Own Inference Layer
Commercial AI APIs already exist, so it is fair to ask why a national lab should run its own. Three answers are visible in the structure of the announcement. First, data governance: much scientific data is subject to policies that make shipping it to a commercial endpoint complicated or impossible, and an in-house service keeps sensitive or export-controlled data inside the fence. Second, cost and predictability: at the volumes scientific workflows can generate, metered commercial pricing becomes a research-budget problem, while a shared national resource spreads cost across the community. Third, reproducibility: open science depends on knowing exactly which model, at which version, produced a result — control that is easier to guarantee on infrastructure the community operates itself.
The counterweight is that operating inference infrastructure well is hard, and commercial providers iterate faster than public procurement cycles. Whether a lab-run service can keep pace with frontier commercial offerings — in model quality, tooling, and reliability — is the open competitive question, and the release, as available to us, does not yet provide the evidence to judge it.
The Infrastructure Signal: Inference Is Becoming a Baseload Workload
For the data-center industry, the notable thing is what this says about demand. Training gets the headlines, but inference is the workload that persists after the training run ends — continuous, growing with adoption, and increasingly treated as critical infrastructure. When a national laboratory stands up dedicated large-scale inference capacity, it confirms that inference is no longer an afterthought riding on spare cycles; it is a planned, provisioned workload with its own power, cooling, and availability requirements.
That has knock-on effects for everyone who builds and operates facilities. Inference favors sustained utilization and low-latency proximity to users and instruments, which shapes site selection and network design differently than training campuses do. Public-sector entrants also add a new class of buyer for accelerators and serving software — one whose requirements (openness, auditability, long service lifetimes) differ from the hyperscalers’. Vendors who can meet those requirements gain a market; those optimized purely for commercial serving economics may find the fit imperfect.
Background
Argonne National Laboratory, founded in 1946 and located outside Chicago, is one of the U.S. Department of Energy’s largest science and engineering research centers. Its Argonne Leadership Computing Facility provides supercomputing to researchers nationwide through peer-reviewed allocations, and in recent years the lab has been a focal point of DOE’s push into exascale computing and AI for science, including early testbeds for emerging AI accelerator hardware.
That history matters because national labs have traditionally delivered computing as scheduled batch time on flagship machines. The move to an always-on inference service represents the research-computing world adopting the service-oriented operating model that commercial AI platforms pioneered — a shift several labs have discussed, and which Argonne now claims to be first to deliver at large scale for open science.
A farm county in southeast Nebraska has put new data centers on hold for up to a year. Data centers are the huge warehouse-like buildings full of computers that run artificial intelligence.
Residents were alarmed by reports of a Google plan for a Nebraska facility that could use more than three times the electricity of the entire city of Lincoln on a hot summer day. They asked about water, power bills and heat.
A new state law now gives counties a deadline to rule on some projects. Counties without rules may pause first and write rules later.
The Otoe County Board of Commissioners in southeast Nebraska voted on Tuesday, May 19, to suspend the permits needed for a new data center for up to a year, Nebraska Public Media reported, carrying reporting by the Flatwater Free Press. Commissioner Chuck Cole said the pause is meant to give county officials time to study the issue and update county regulations.
The vote followed local concern about a Google proposal for a large Nebraska data center. According to documents shared at a private utility meeting in January, that facility could require more than triple the electricity the city of Lincoln uses during its hottest months. The proposal did not name a site. The Omaha-based energy developer Tenaska, described as a potential partner, has optioned large tracts of land in southeast Nebraska, including in Otoe and Gage counties. Gage County’s planning and zoning commission is scheduled to hold a hearing on its own moratorium in June.
Executive Summary
Otoe County has not rejected data centers. It has stopped issuing the permits for one while it writes rules it does not yet have. That distinction matters to anyone planning large AI facilities in rural America. The practical obstacle in Otoe is not a lack of electricity or land. It is the absence of a local rulebook that can answer residents’ questions about water, power costs and heat before a project arrives.
Two new Nebraska laws raise the stakes. One allows private power plants built to serve a single large industrial customer to connect to the grid. That law is widely seen as aimed at data centers and was backed by Tenaska’s CEO at a legislative hearing. The other law requires counties to rule on some projects within a fixed period. Jon Cannon of the Nebraska Association of County Officials said that deadline may prompt counties to adopt moratoriums first so they are not forced to rule without regulations in place.
Otoe is one of several signals. Madison County now requires a special permit for data centers, Gage County is weighing a pause, and, according to the report, at least 14 states have considered statewide moratoriums this year.
A Pause to Write Rules, Not a Permanent No
A moratorium is a temporary halt on a category of approvals. Otoe’s suspends data center permits for up to a year. The board framed it as time to study the issue and update its regulations, not as a verdict on the industry. Wynee Benedict, one of the residents who pushed for it, described the goal in regulatory terms: “We needed regulations on the books prior to a data center coming to this county. We don’t want to have to play catch up and regulate something that’s already here.”
Residents did not all agree. Jim Nemec supported time to study the issue but warned about the signal it sends: “Are we sending out the impression that business is closed here?” That is a fair concern. A county that pauses without a clear end date, or that uses the year to write rules nobody can meet, risks becoming a place developers skip. A county that uses the year to publish clear standards on water, noise, setbacks and power costs may become an easier place to build than one with no rules at all. Setbacks are required distances from homes or roads. The ordinance the county drafts will matter more than the vote itself.
Why AI Siting Now Runs Through the County Board
This is the core of the story. The scale being discussed in southeast Nebraska is large. The Google proposal could require more than triple Lincoln’s summer electricity use, and the organizers in Gage County said they understood it would include a private natural gas plant. At that size, a project needs the grid connection, the generation, the land and the local land-use permit. The state has now eased the power question by allowing private generation dedicated to a large customer. Tenaska has reportedly secured land options, which are contracts giving it the right to buy or lease land later. The piece still in doubt is the county permit, and in Otoe that piece is now frozen for up to a year.
The state’s new decision-deadline law pushes counties in the same direction. It was intended to stop counties from stalling projects indefinitely. But a county with no data center rules that faces a firm deadline to decide on an application has two choices: rule without standards, or pause until it has them. Cannon expects many to pause, and not only for data centers. For developers this matters a great deal. A law designed to shorten approvals could lengthen them in counties that are not ready, and in the short term the counties that are not ready are most of the rural counties where land and gas access make these projects attractive.
This should not be overstated. One county’s vote is not a statewide trend, and Cannon himself said attitudes will vary from county to county, as they have for wind and solar. But Otoe, Madison and Gage have all acted or scheduled action within weeks of each other, and all three are responding to the same prospect. That points to county zoning as the next checkpoint for rural AI campuses, alongside power and fiber.
Power Was Handled in Lincoln; Water Was Left to the Counties
Nebraska’s legislature and Gov. Jim Pillen addressed the energy question directly. The private-generation law is meant to keep large new loads from burdening existing ratepayers. Virginia shows what happens when this goes unaddressed. Joe Lerch of the Virginia Association of Counties said the state’s main utility has had to postpone connecting some new data centers for lack of power and transmission capacity.
Water got no equivalent state-level answer, and in Otoe and Gage it is the concern residents raise first. Gage County organizer Anna Wolken said the top issue would be water, because both a gas plant and a data center can draw on it. Gas plants use water for cooling, and many data centers use water to carry heat away from their servers. How much depends heavily on the cooling design. Air-based and closed-loop systems use far less than evaporative ones. Nobody involved has said publicly which approach the proposed facility would use.
A separate transparency law will require data centers to report their owners, size, location, annual electricity demand, water use and tax incentives each year. That gives county officials comparable data for future decisions. It does not help a county decide on a first project before any such reports exist, which is exactly Otoe’s situation.
What Developers Can Take From Otoe
Cannon’s advice to developers was practical: tell residents early. He described what happens when neighbors learn about a project from each other, through someone who “just signed this big contract for a right of way.” In Otoe and Gage, residents appear to have learned of the potential project through press reporting on a private utility meeting and through land options. It was not an announcement from the companies. A community that pieces a project together from secondhand reports tends to fill the gaps with worst-case assumptions.
The lesson for anyone siting AI capacity in rural areas is that the time-consuming work may be local rather than technical. That means disclosing water and cooling plans, explaining who pays for power, and engaging before the zoning agenda is set. Developers who bring those answers to a county writing its first ordinance have a chance to help set the terms. Developers who arrive afterward will be working within rules written without their input.
Background
Otoe County sits in southeast Nebraska. Its county seat is Nebraska City, south of Omaha and east of Lincoln. Like many rural counties, it has previously dealt with controversial large developments such as wind and solar farms. Its land-use rules were not written with hyperscale data centers in mind. Hyperscale refers to the very large facilities built by major cloud and AI companies.
Demand for AI computing has driven a nationwide search for sites with available land, power and water. Established hubs such as Northern Virginia have run into grid limits. Nebraska responded in 2026 with a law allowing dedicated private power generation for large customers and a separate law requiring annual public reporting on data center energy and water use.
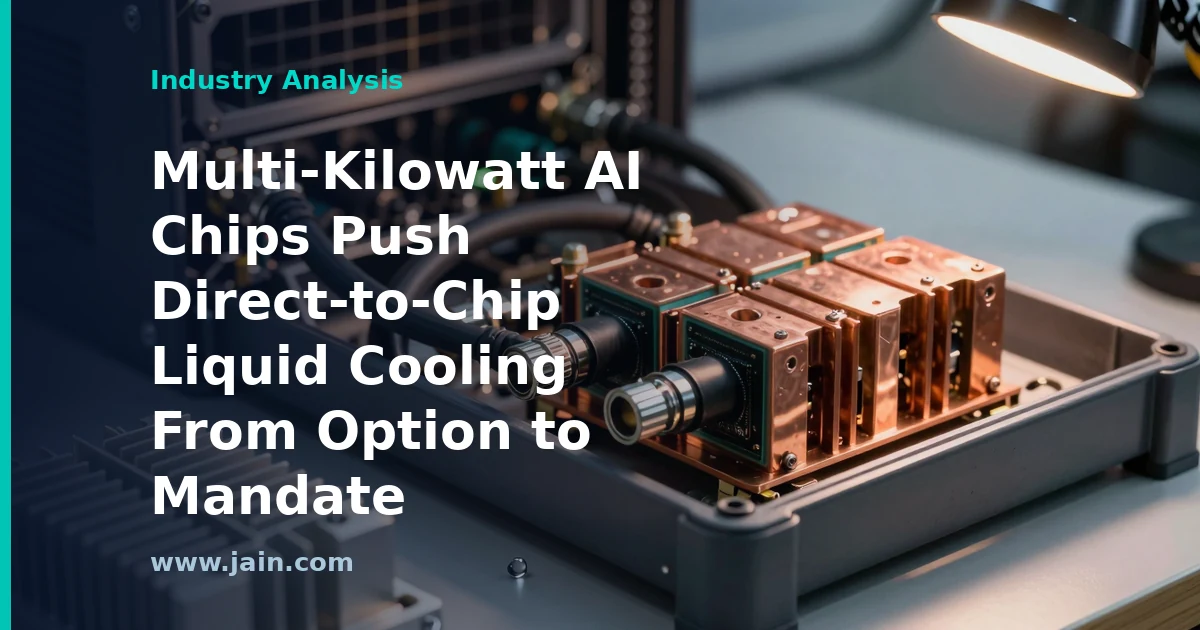
Engineering trade publication Electronics360 published an analysis on May 24, 2026 arguing that direct-to-chip (D2C) liquid cooling — circulating coolant through cold plates mounted directly on processors — has crossed from a design option to a practical requirement, driven by AI accelerator chips whose power draw has reached the multi-kilowatt range per device.
The piece frames this as the end of an era: air cooling, the default thermal strategy for data centers since the industry’s beginning, can no longer keep pace with the heat that flagship AI silicon produces in the small area of a single chip package.
Executive Summary
The core claim is thermodynamic rather than commercial: individual AI processors now dissipate thousands of watts each, and moving that much heat out of a dense rack with air alone requires airflow volumes and temperature differentials that become impractical or impossible at the densities AI clusters demand. Direct-to-chip liquid cooling, which places a liquid-filled cold plate against the chip itself, removes heat far more efficiently because liquids carry heat orders of magnitude better than air.
Why it matters: if D2C is genuinely mandatory rather than optional, every layer of the data-center stack changes — facility design, plumbing, power distribution, rack architecture, maintenance skills, and capital budgets. Operators of existing air-cooled facilities face retrofit decisions, and new builds are being designed liquid-first. For an industry that standardized on air handling for decades, this is a foundational transition, not an incremental upgrade.
Physics Ended the Debate Before the Market Did
Air cooling persisted as the default not because it was elegant but because it was cheap, simple, and universally understood. Its limitation is fundamental: air is a poor heat conductor, so cooling a hotter chip means moving more air, faster, across larger heatsinks. As AI accelerators pushed past one kilowatt per device — with roadmaps pointing well beyond — the heat concentrated in a few square centimeters of silicon began to exceed what any realistic airflow can absorb. Water and engineered coolants transfer heat dramatically more effectively, which is why cold plates bolted directly onto the chip package have become the pragmatic answer.
The word ‘mandatory’ in the source’s framing is worth taking seriously but precisely. Air cooling is not disappearing from data centers generally — the vast installed base of conventional enterprise and cloud workloads runs at rack densities air handles fine. The mandate applies to the frontier: dense AI training and inference clusters built around multi-kilowatt accelerators. That distinction matters for anyone budgeting a transition.
The Retrofit Question Splits the Market
Liquid-first design is straightforward in a new build: coolant distribution units, manifolds, leak detection, and higher floor loading are engineered in from day one. Retrofitting an existing air-cooled facility is harder. Piping must be routed through spaces never designed for it, water supply and heat-rejection capacity must be added, and operations teams must learn to manage a system where a leak — rare but nonzero — sits inches from expensive silicon.
This creates a divergence in asset value across the industry. Facilities that can economically accept liquid cooling — because of their power capacity, structure, and location — become more valuable as AI demand grows. Older facilities that cannot may be relegated to lower-density workloads. Colocation providers, hyperscalers, and enterprise operators are all making that assessment now, and the answers will shape which real estate wins the AI buildout.
A New Supply Chain Rises Around the Cold Plate
A shift of this scale redraws the vendor landscape. Demand moves toward cold plates, coolant distribution units, quick-disconnect fittings, dielectric and water-based coolants, leak-detection systems, and rear-door or facility-level heat exchangers — categories that were niche a few years ago. Established thermal-management and precision-cooling vendors are competing with newer specialists, and chip and server makers increasingly ship liquid-ready designs, effectively deciding the question for their customers.
There is also an efficiency dividend. Because liquid captures heat at the source, less energy is spent on fans and air handling, and the warm coolant leaves at temperatures useful for heat reuse in some settings. For operators facing scrutiny over data-center energy consumption, D2C offers a genuine efficiency story — though it introduces its own considerations around water use and coolant handling that deserve equally honest accounting.
Background
For most of computing history, data centers were cooled the same way: chilled air pushed through raised floors or ducts, across finned metal heatsinks, and back to air-handling units. That model worked because individual chips drew tens or hundreds of watts. The AI era broke the assumption — training and running large models rewards packing the most powerful accelerators as densely as possible, and each generation of AI silicon has raised per-chip power substantially, crossing the kilowatt mark and continuing upward.
Liquid cooling itself is not new; mainframes and supercomputers used water cooling decades ago before commodity air-cooled servers displaced them on cost. What has changed is that the physics that once made liquid cooling a supercomputing niche now applies to mainstream AI infrastructure, pulling a once-specialist discipline back to the center of data-center design.
Source: Multi-kilowatt chips make D2C cooling mandatory — Electronics360 analysis (May 24, 2026) on why multi-kilowatt AI processors are forcing data centers from air cooling to direct-to-chip liquid cooling.
Reuters reported on May 24, 2026 that Schneider Electric — the French energy-management and industrial-automation group — says its data center business in India is now growing faster than its core business, propelled by the country’s AI-driven data center buildout. The comment positions India as one of the standout markets in a global surge of demand for the electrical equipment that powers AI computing.
Executive Summary
The substance of the report is a growth signal, not a contract or a capacity announcement: Schneider Electric, one of the world’s largest suppliers of the switchgear, uninterruptible power supplies (UPS — the battery-backed systems that keep servers running through grid disturbances), and power-distribution equipment that data centers depend on, says demand from India’s data center sector is expanding faster than the rest of its business there.
That matters for two reasons. First, it is a read on where the AI infrastructure wave is spreading: hyperscale-style demand is no longer confined to the United States and a handful of established hubs. Second, it comes from the supply side. Data center operators announce ambitions; equipment vendors see purchase orders. When a major electrical supplier says one segment is outgrowing everything else it does in a market, that is a comparatively hard signal that capital is actually being spent.
The caveat is proportionality: “outpacing core growth” describes a rate, not a size, and the report as available does not quantify either. A fast-growing segment can still be a small one.
The AI Boom Is Really an Electrical Equipment Boom
Every AI data center is, underneath the servers, an electrical engineering project. Racks of AI accelerators draw several times the power of conventional servers, and that power has to be received from the grid, transformed, distributed, conditioned, and backed up — all with equipment from a fairly short list of global vendors, of which Schneider Electric is one of the largest alongside the likes of ABB, Siemens, Eaton, and Vertiv. This is why the AI cycle has been felt so strongly by electrical suppliers: compute demand converts almost directly into orders for switchgear, transformers, UPS systems, busway, and cooling infrastructure.
Schneider’s India comment extends a pattern the industry has watched for two years in the US and Europe: the constraint on AI capacity is increasingly power delivery, not chips alone. When equipment vendors describe data centers as their fastest-growing segment in a new geography, it signals that the buildout — and potentially the associated equipment lead-time pressure — is going global.
Why India Is the Market to Watch
India combines several ingredients that data center investors look for: a very large and growing base of internet users, data-localization rules that encourage storing Indian data in-country, comparatively low construction costs, and government interest in domestic AI capability. Global cloud providers and regional operators have all announced Indian expansion in recent years, concentrated around hubs such as Mumbai, Chennai, and Hyderabad.
For an equipment vendor, India offers something else: Schneider Electric has a long-established manufacturing and commercial presence there, so local data center demand can be served substantially from local operations. If AI-driven orders are now growing faster than the company’s traditional Indian business — which spans buildings, industry, and grid infrastructure — it suggests the data center segment is becoming a structural growth pillar rather than a side market.
Supply-Side Signals Deserve Attention — and Context
It is worth being precise about what this report does and does not establish. A vendor saying a segment is “outpacing core growth” is a directional claim about relative growth rates. As reported, it does not disclose the segment’s revenue, its share of Schneider’s India business, order backlog, or a forecast horizon. Growth from a small base can outpace a large core for years without changing the overall business mix, so the claim is credible but not yet quantified in the material available.
It is also a statement any vendor has an interest in making during an AI investment cycle: data center exposure is currently rewarded by investors. That does not make the claim wrong — Schneider’s global results through this cycle have consistently shown genuine data center strength — but buyers and investors should look for the numbers behind the narrative when the company next reports segment detail. For data center operators, the practical takeaway is less about Schneider specifically and more about the market it describes: if India’s buildout is accelerating, competition for equipment, grid connections, and skilled electrical contractors in that market will accelerate with it.
Background
Schneider Electric traces its roots to 1836 in France and has evolved from heavy industry into a global leader in energy management and automation. Its data center relevance deepened with the 2007 acquisition of APC, a leading UPS maker, and the company now supplies integrated power, cooling, and management systems to hyperscale and colocation operators worldwide. Throughout the current AI investment cycle, data centers have been among the strongest demand drivers across the electrical equipment industry.
India’s data center market has expanded rapidly since the country’s 2020s push on data localization and digital infrastructure, attracting investment from global cloud providers and domestic operators alike. The AI wave has added a second demand layer on top of that cloud-driven growth, with power availability widely viewed as the buildout’s key constraint.
RTO Insider reported on May 24, 2026 that grid researchers are examining the long-term future of natural gas plants built quickly to serve data centers — the generation category that has become the default answer to AI-driven electricity demand across U.S. power markets. The piece frames a question now central to utility and grid-operator planning: what happens to a fleet of fast-build gas plants over the decades after the immediate data-center crunch they were built to solve?
Executive Summary
The report, published by RTO Insider — a trade outlet covering regional transmission organizations (RTOs), the entities that run wholesale electricity markets and the high-voltage grid across much of the United States — captures a debate that has moved from the margins to the center of power-sector planning. Data-center developers facing multi-year waits for grid interconnection have increasingly turned to natural gas generation, often sited at or near the data center itself, because gas turbines can be permitted and installed faster than almost any other firm, dispatchable power source at comparable scale.
That researchers are now asking what becomes of these plants matters because the answer shapes who bears the cost. A gas plant is a decades-long asset being built to serve a demand surge whose duration nobody can guarantee. Whether these units become permanent baseload, transition into backup and peaking roles as cleaner firm power arrives, or end up underused, will determine outcomes for utilities, ratepayers, data-center operators, and the emissions trajectory of the AI build-out. The syndicated version of the article available to us carries only the headline, so the specific researchers, markets, and findings involved are not detailed here — but the question itself is well documented across the industry, and it deserves examination on its own terms.
Speed to Power Is the Whole Ballgame
The reason gas keeps winning data-center deals is not ideology or even, primarily, fuel economics — it is time. In several major U.S. markets, connecting a large new load or generator to the grid can take years of interconnection study and transmission upgrades. A hyperscale AI campus that needs hundreds of megawatts cannot wait that long when the competitive race in AI is measured in quarters. Gas turbines, including smaller aeroderivative and reciprocating-engine units, can often be deployed in a fraction of the time, sometimes ‘behind the meter’ — meaning on the customer’s side of the utility connection, serving the facility directly rather than flowing through the shared grid.
Nuclear cannot be built quickly; new large hydro is essentially unavailable; wind and solar are fast but intermittent, and pairing them with enough storage to run a 24/7 AI facility remains expensive at gigawatt scale. That leaves gas as the pragmatic default — which is precisely why researchers are scrutinizing what the industry is committing itself to by default rather than by design.
A Bridge Needs a Far Shore
Calling gas a ‘bridge fuel’ — a transitional energy source used until cleaner firm power scales up — embeds an assumption: that something is on the other side of the bridge. Candidates include advanced nuclear (including small modular reactors), enhanced geothermal, long-duration storage, and gas units retrofitted for carbon capture or hydrogen blending. All are promising; none is deployable today at the pace and price the AI build-out demands. If those technologies mature on schedule, fast-build gas plants can gracefully shift from running constantly to running occasionally, as peakers and reliability backstops. If they do not, the ‘bridge’ quietly becomes the destination, with the associated locked-in emissions and fuel-price exposure.
The honest answer — and likely part of why researchers are ‘pondering’ rather than concluding — is that both outcomes are live possibilities, and the difference is worth billions of dollars and a meaningful slice of U.S. emissions.
Who Holds the Asset Risk?
The economics hinge on who owns the plant and who pays if demand disappoints. When a data-center developer builds its own on-site generation, the stranded-asset risk — the danger of an expensive asset losing its economic purpose before it is paid off — sits largely with a private company that chose it. When a regulated utility builds gas capacity into its rate base to serve forecast data-center load, ordinary ratepayers can end up carrying the cost if AI demand forecasts prove inflated or if a customer leaves. Grid operators and state regulators are actively developing large-load tariffs, minimum-take contracts, and exit fees to allocate that risk more explicitly, and the research attention RTO Insider describes feeds directly into those proceedings.
Supply chains add another wrinkle: demand for heavy-duty gas turbines has surged worldwide, and lead times for new orders have stretched to several years. That erodes some of gas’s core speed advantage and pushes developers toward smaller, modular units — machines that are, conveniently, also easier to redeploy or run flexibly if the long-term role of these plants shrinks.
What It Means for the Data-Center Industry
For data-center operators and their customers, the takeaway is that power strategy is now inseparable from business strategy. Facilities powered by fast-build gas gain schedule certainty today but inherit questions about fuel-cost volatility, future emissions regulation, and the sustainability commitments of the tenants they serve — many large technology companies maintain public carbon-free-energy targets that on-site gas complicates. Operators that pair near-term gas with credible contracts for cleaner firm power, or that site where grid capacity genuinely exists, will have an easier story to tell enterprise customers, regulators, and communities. The infrastructure sector should welcome the scrutiny: a clear-eyed answer to ‘what happens to these plants in 2040?’ is better arrived at before the concrete is poured than after.
Background
After roughly two decades of flat U.S. electricity demand, the AI data-center build-out has triggered the fastest load-growth forecasts utilities have issued in a generation, with individual campuses now requesting hundreds of megawatts — and some multi-gigawatt projects proposed. Grid interconnection queues, transmission construction timelines, and generator retirements have collided with that surge, making ‘speed to power’ the defining constraint of the data-center industry. Natural gas, which already supplies the largest share of U.S. electricity generation, has emerged as the default fast answer, spawning a wave of proposed on-site and utility-scale gas projects. RTO Insider, the outlet behind this report, covers the regional transmission organizations and regulatory proceedings where the resulting cost, reliability, and emissions questions are being fought out.
Nebius, the AI infrastructure company spun out of the former Yandex, has agreed to deploy up to 328 megawatts of Bloom Energy solid-oxide fuel cells to power its U.S. AI data center expansion, according to a report published May 24, 2026.
The arrangement positions on-site fuel cells as a bridge power source while Nebius scales GPU capacity in a market where utility interconnection timelines routinely stretch to five years or more.
Executive Summary
The 328 MW figure is significant. It is roughly the electrical draw of a mid-sized hyperscale campus, and it lands at a moment when AI-driven compute demand is outrunning the pace at which U.S. utilities can deliver new substations and transmission upgrades. By procuring behind-the-meter generation, Nebius is buying schedule certainty — trading potentially higher lifetime energy costs for the ability to energize racks on its own timetable.
For Bloom Energy, a Nebius commitment at this scale reinforces a thesis the company has pitched to Wall Street for two years: that fuel cells, historically a niche resiliency product, have found a mainstream buyer in AI. The deal also plants a flag for gas-fueled distributed generation in a segment often assumed to be dominated by renewables and long-duration storage.
Nebius is a watchlist name for infrastructure investors precisely because it is trying to establish itself as a Western pure-play AI cloud without the balance sheet of a hyperscaler. Power procurement is one of the clearest tests of whether that plan can scale.
Why Fuel Cells, Why Now
Solid-oxide fuel cells convert natural gas — or, in principle, hydrogen or biogas — into electricity through an electrochemical reaction rather than combustion. That makes them quieter than reciprocating engines, cleaner than diesel generators on criteria pollutants, and, crucially, deployable in modular blocks over months rather than the years it takes to build a substation. For an AI operator racing to install GPUs before the next model generation renders current capacity uncompetitive, that speed premium can justify a higher levelized cost of energy.
The economics still depend on assumptions the release does not spell out: gas prices at the delivery site, capacity factor, whether the fuel cells serve as primary power or bridge to a future grid tie, and how carbon is accounted for. Fuel cells emit CO2 when fed pipeline gas, even if they avoid the NOx penalties of engines. That matters for customers with science-based targets and for regulators in states tightening data center emissions rules.
The Nebius Growth Story Gets Its Power Test
Nebius has positioned itself as a neocloud — a category of GPU-first infrastructure providers, including CoreWeave and Crusoe, competing to rent Nvidia capacity to model developers and enterprises. The market rewards these names for signed capacity and rewards them further for capacity that is actually energized and generating revenue. Announcements of GPU orders without a credible power path have grown less impressive to investors over the past year.
A 328 MW behind-the-meter arrangement addresses that skepticism directly. It does not, however, resolve questions about financing structure, siting, or whether the megawatts are contracted, optioned, or contingent on further milestones. Investors will want to see how the commitment is reflected in Nebius’s capex guidance and whether Bloom is a supplier, a project partner, or both.
Winners, Losers, And The Grid Question
The clearest short-term winner is Bloom Energy, which converts a marquee AI reference into a validation point for future data center pursuits. Gas producers and midstream operators benefit indirectly if the pattern spreads. Utilities are more ambiguous: they lose a large potential load in the near term, but they also lose the political burden of finding transmission capacity for it.
The loser, if any, is the tidy narrative that AI infrastructure will be powered predominantly by new renewables plus storage. On-site gas generation is expedient, and expedient often wins when demand is measured in quarters. The counter-argument — that fuel cells can eventually run on hydrogen or biogas — is technically valid but depends on fuel supply chains that do not yet exist at scale.
Background
Nebius is one of a handful of pure-play AI infrastructure companies competing with hyperscalers to lease Nvidia GPU capacity to model developers. Its scale ambitions in the United States hinge on securing power quickly in a market where utility interconnection timelines have become the binding constraint on data center growth.
Bloom Energy has sold solid-oxide fuel cells for more than a decade, initially as resiliency and prime-power equipment for enterprises and utilities. Over the past two years the company has repositioned as a data center power supplier, arguing that its modular systems can be deployed years faster than new grid capacity.
Nvidia’s revenue grew 85% on the strength of AI infrastructure demand, according to a CIO Dive report published May 22, 2026. The figure — the only quantified data point in the report as surfaced — points to enterprises and cloud providers continuing to buy AI compute at a pace few hardware markets have ever sustained.
Executive Summary
An 85% revenue jump at a company already among the world’s largest chipmakers is not a startup doubling off a small base. At Nvidia’s scale, that percentage implies tens of billions of dollars in incremental sales, driven — per the report — by demand for AI infrastructure: the GPUs (graphics processing units repurposed as AI accelerators), networking gear, and integrated systems used to train and run artificial-intelligence models.
The number matters beyond Nvidia’s shareholders because Nvidia sits at the front of the AI build-out pipeline. Every accelerator it ships must eventually land in a rack, draw power, be cooled, and be connected. A growth rate like this is therefore a leading indicator for data center construction, electricity demand, and colocation absorption — the downstream industries that turn chips into working AI capacity.
That said, the source is a headline-level report with a single figure. It does not, as surfaced, disclose absolute revenue, the fiscal period covered, segment mix, margins, or guidance — all of which determine whether this print signals accelerating demand or the tail end of a catch-up cycle. Our analysis works within those limits.
Growth at This Scale Is a Demand Signal, Not a Rounding Error
The law of large numbers says percentage growth should fall as a company gets bigger. Nvidia posting 85% growth despite already dominating the AI accelerator market suggests the pull from AI infrastructure buyers remains intense: cloud providers, model developers, and increasingly mainstream enterprises are still racing to secure training capacity (the compute used to build AI models) and inference capacity (the compute used to run them for users).
What a single growth rate cannot tell you is trajectory. Without the absolute figures or prior-quarter comparisons, an 85% jump could represent acceleration, steady state, or deceleration from even hotter periods earlier in the AI cycle. It also cannot distinguish broad-based enterprise adoption from a handful of hyperscale customers placing enormous orders — a distinction that matters greatly for how durable the demand is. The honest reading of this report is directional: demand remains strong enough to move one of the world’s largest revenue bases by nearly half again.
The Squeeze Moves Downstream: Power, Cooling, and Floor Space
Chips are only the first link in the AI supply chain. Each generation of AI accelerators draws more power per rack than the last, pushing many deployments beyond what traditional air cooling handles and toward liquid cooling. When Nvidia’s revenue grows 85%, the practical consequence is a wave of hardware that needs megawatts of grid capacity, high-density data center space, and dense fiber connectivity — resources that take years, not quarters, to build.
For the infrastructure industry, that makes this print quietly bullish: data center operators, power-infrastructure providers, cooling vendors, and network carriers all sit downstream of Nvidia’s shipments. It also relocates the bottleneck. In the early AI boom the constraint was chip supply; increasingly, the constraint is where to plug the chips in. Buyers evaluating AI deployments should read Nvidia’s growth as a warning that competition for powered, cooled capacity is intensifying alongside competition for the silicon itself.
Concentration Cuts Both Ways
Nvidia’s position rests heavily on its CUDA software ecosystem — the programming platform that most AI frameworks target — which raises switching costs even when rival hardware is competitive on paper. But 85% growth is also the kind of number that motivates alternatives: rival merchant chipmakers, and the custom accelerators that large cloud providers design in-house to reduce dependence on a single supplier. The bigger the prize, the harder others will work to claim a share of it.
Concentration on the buyer side deserves equal scrutiny. Industry-wide, a large share of AI infrastructure spending flows from a small set of hyperscale companies, and order patterns from a few buyers can swing a supplier’s results sharply in either direction. The report offers no customer breakdown, so neither the bullish case (broadening enterprise demand) nor the cautious one (dependence on a few giant purchasers) can be confirmed from this source. Both remain fair questions to hold open.
Background
Nvidia, founded in 1993, spent its first decades known mainly for gaming graphics cards. Its parallel-processing GPUs proved ideal for the deep-learning techniques that took off in the 2010s, and its CUDA software platform became the default foundation for AI development. When generative AI demand exploded after 2022, Nvidia’s data center business became its dominant revenue driver and the company rose into the ranks of the world’s most valuable firms, with successive accelerator generations selling out to cloud providers and AI developers.
The broader market context is a global AI infrastructure build-out in which chip purchases, data center construction, and power procurement have become tightly linked: chip revenue at Nvidia today generally foreshadows demand for space, megawatts, and cooling across the data center industry tomorrow.
Google has announced a $15 billion data center expansion in Missouri, and — notably — the company is pairing the buildout with explicit power commitments and protections for utility ratepayers, according to a May 22, 2026 report by POWER Magazine. The pledge positions one of the world’s largest cloud and AI operators as a partner in managing the grid impact of its own growth, rather than simply a very large new electricity customer.
Executive Summary
The headline number is striking on its own: $15 billion is a top-tier hyperscale commitment, the kind of figure that historically flowed to established data center markets like Northern Virginia or central Ohio. Directing it to Missouri continues a broader migration of AI-era infrastructure toward interior states with available land, power, and political goodwill.
But the more consequential part of the announcement may be the framing. By foregrounding power commitments and ratepayer protections, Google is acknowledging the central tension of the AI infrastructure boom: data centers are now large enough to move electricity prices and strain grid planning, and communities have noticed. Structuring a megaproject so that existing utility customers are shielded from its costs — at least as pledged — is emerging as the price of admission for hyperscale development, and this deal reads as a template for that era.
Ratepayer Protection Is Becoming the Price of Admission
For most of the data center industry’s history, electricity was a procurement detail. That changed as AI training and inference pushed individual campuses toward the power draw of small cities. Utilities must build generation and transmission to serve that load, and under traditional regulated-utility economics, those costs can be spread across all customers — meaning households could subsidize infrastructure built primarily for a trillion-dollar technology company. Regulators, consumer advocates, and legislatures in several states have pushed back, demanding special tariff classes, minimum-payment contracts, and cost-allocation guarantees for large loads.
Google publicly committing to ratepayer protections up front, rather than having them imposed in a contested rate case, is therefore strategically significant. It shortens the approval path, lowers political risk, and sets a benchmark competitors will likely be measured against. The caveat: a headline pledge is not a tariff. What ‘ratepayer protection’ means in practice depends on binding terms filed with regulators, and the report available to us does not detail those terms.
Why Missouri, and Why Now
Missouri is not a legacy data center hub, and that is increasingly the point. The traditional markets are constrained — grid interconnection queues stretch for years, land prices have soared, and local opposition has hardened. Interior states offer buildable land, room on the transmission system, fiber routes crossing the middle of the country, and governments eager for capital investment and construction activity. A $15 billion commitment would instantly place Missouri among the more significant AI infrastructure destinations in the region.
For the state, the bargain is jobs, tax base, and relevance in the AI economy, weighed against long-lived demands on power and, typically, water for cooling. The durability of that bargain depends heavily on the details this announcement previews but does not fully disclose: how much generation gets built, who owns it, and how firmly the cost shield for existing customers is written.
The Economics of Pledging Power, Not Just Buying It
An explicit ‘power commitment’ from a hyperscaler can take several forms: funding or contracting for new generation, paying for transmission upgrades, guaranteeing minimum offtake so utilities can finance construction without stranding costs on other customers, or bringing dedicated supply behind the meter. Each shifts risk from the public to the developer in a different way, and each has different implications for how fast capacity actually arrives. Hyperscalers have learned that power availability — not chips, not concrete — is now the binding constraint on AI growth, so paying to expand supply is self-interested as much as civic-minded.
For the wider industry, deals like this raise the bar. Smaller operators and colocation providers cannot underwrite generation the way an Alphabet can, which could bifurcate the market: hyperscalers who bring their own power solutions, and everyone else competing for whatever grid headroom remains. Utilities, meanwhile, gain a rare growth story — if regulators can verify that growth genuinely pays its own way.
Background
Google has spent more than two decades building one of the world’s largest data center footprints, and the generative-AI boom that began in late 2022 pushed its infrastructure spending — like that of Microsoft, Amazon, and Meta — to unprecedented levels. As easy grid capacity in traditional hubs ran short, hyperscalers fanned out across interior states, turning electricity availability into the industry’s defining constraint.
That expansion has collided with utility economics. In multiple states, regulators and consumer groups have questioned whether households end up subsidizing grid buildouts made for tech giants, prompting special large-load tariffs and contract protections. Google’s Missouri announcement lands squarely in that debate, presenting itself as the cooperative model: hyperscale growth that pledges to pay its own way.
Modal Labs, a startup that provides serverless infrastructure for artificial-intelligence workloads, has closed a $355 million funding round, as reported by SiliconANGLE on May 22, 2026. The round ranks among the larger financings to date for the emerging category of companies that let developers run GPU-powered AI code without managing the underlying servers.
Executive Summary
The announcement is straightforward: Modal Labs has secured $355 million in new funding. What makes it worth attention is the category it validates. “Serverless” computing means developers submit code and pay only for the seconds it actually runs, while the provider handles provisioning, scaling, and scheduling of the machines underneath. Applying that model to GPUs — the expensive, supply-constrained accelerator chips that power AI training and inference — is a harder engineering problem than classic serverless, and until recently most AI teams simply rented GPU servers by the month and absorbed the idle time.
A round of this size suggests investors believe the orchestration layer — the software that decides which workload runs on which GPU, and when — is becoming its own durable tier of the AI infrastructure stack, sitting between raw compute providers and the applications built on top. For data-center operators, GPU cloud providers, and enterprise buyers, that thesis has real implications for how AI capacity gets bought, priced, and utilized.
The Economics of Idle Silicon
The core problem serverless GPU platforms attack is utilization. High-end AI accelerators are among the most expensive line items in modern computing, and a GPU reserved around the clock but busy only a fraction of the time is capital burning quietly. Inference workloads — running a trained model to answer live requests — are especially bursty: traffic spikes and lulls make fixed reservations wasteful. A platform that pools GPUs across many customers and bills per second of actual execution converts that stranded capacity into revenue, and converts a customer’s fixed cost into a variable one.
That is the same economic argument that made serverless computing successful for ordinary CPU workloads a decade ago. The difference is difficulty: AI models can take tens of gigabytes of memory and long seconds to load, so starting them on demand — the “cold start” problem — requires genuine systems engineering. Solving it well is the moat companies in this category are selling, and a $355 million round indicates at least some investors believe the moat is real.
A New Layer Between the Chips and the Apps
The AI infrastructure stack has been visibly stratifying: chipmakers at the bottom; hyperscale clouds and specialist GPU cloud providers renting raw capacity; and application companies at the top. Orchestration platforms like Modal occupy the middle — they typically do not fabricate chips or, primarily, build data centers, but abstract other people’s hardware behind a developer-friendly interface. The bet embedded in this funding round is that the middle layer captures durable value, much as earlier developer-platform companies did atop the big clouds.
If the bet pays off, the winners include developers, who get cloud-like elasticity for AI; and, arguably, the upstream capacity providers, who gain a demand aggregator that keeps their fleets busy. The pressure lands on undifferentiated GPU rental businesses, because an orchestration layer that can shift workloads across suppliers commoditizes the raw compute beneath it.
The Risks the Category Still Carries
None of this is guaranteed. The largest cloud providers already offer their own serverless and managed inference products and can bundle them with existing enterprise agreements, so an independent orchestration layer must stay meaningfully better to justify its place. The category also depends on continued access to scarce accelerators at workable prices — a middle layer inherits the supply risk of its suppliers without controlling it. And the industry’s broader trajectory matters: if AI spending growth moderates, richly funded infrastructure startups will be judged on gross margins and retention rather than category narrative. The announcement, as reported, does not include the financial detail needed to assess Modal’s position on those measures, so the size of the round should be read as investor conviction, not as public evidence of unit economics.
Background
Modal Labs emerged in the early 2020s among a wave of startups rethinking developer infrastructure for the AI era, founded by engineers with backgrounds in large-scale data systems. Its platform focused on a specific technical wedge: making heavyweight AI workloads start in seconds inside a serverless model, so developers could treat GPUs the way earlier serverless products let them treat ordinary compute. The company raised conventional venture rounds before this financing and grew alongside the post-2022 boom in generative AI, which turned GPU capacity into one of the technology industry’s scarcest and most expensive resources.
That scarcity reshaped the infrastructure market it operates in. Hyperscale clouds, specialist GPU cloud providers, and a growing middle tier of orchestration and inference platforms now compete to serve AI developers, and utilization — how much of an expensive accelerator’s time is spent doing paid work — has become the economic metric the whole category is organized around.